Turn Ethiopian audio into usable data.
Andebet is the speech intelligence platform for Ethiopian audio. Transcribe, search, and extract structured data from Amharic, Afaan Oromo, Tigrinya, and English recordings.
- 45 free minutes included
- No credit card
- Migrate in one click
Interview with key stakeholders
Audio ID #482 · Processed 2 hours ago
ጤና ይስጥልኝ፣ የዛሬው ውይይታችን በኢትዮጵያ የዲጂታል ቴክኖሎጂ እድገት ላይ ያተኩራል። Good morning, today's interview session focuses on speech AI adoption and multilingual audio transcription across Ethiopia.
Trusted by researchers, journalists & engineering teams
Global transcription models fail on Ethiopian languages.
Off-the-shelf Whisper and global speech models struggle with Ge'ez fidel orthography, Ethiopian dialect variations, rapid code-switching, and local acoustic environments. Words are missed, punctuation fails, and critical research context is lost.
Languages get mixed
Amharic, English, Afaan Oromo and more can appear in the same conversation.
Real recordings aren't perfect
Background noise, accents, interruptions and imperfect microphones are normal.
Context gets lost
Names, places, timestamps and speakers matter. Andebet is built around these realities.
Drop in an interview. Get the conversation back.
Upload your audio files, and let our advanced AI transcribe, translate, and extract insights automatically. Stop manually transcribing your interviews and meetings.
 Telegram Claude & MCP
 WhatsApp
 REST Endpoints Telegram Bot WhatsApp Audio REST API
 GitHub Claude Desktop Telegram Claude & MCP WhatsApp REST Endpoints Telegram Bot WhatsApp Audio REST API GitHub Claude Desktop Twilio Audio Audio Chunker Amazon S3 TypeScript SDK Webhooks Zoom Audio Google Drive MCP Protocol Twilio Voice Twilio Audio Audio Chunker Amazon S3 TypeScript SDK Webhooks Zoom Audio Google Drive MCP Protocol Twilio Voice
01. Drop any audio
Upload any Ethiopian audio format, from WhatsApp voice notes to professional recordings. We handle the rest.
Andebet transcribed this interview · 02:4502. AI Transcription
Tuned for Ethiopian accents, natural code-switching, and Ge'ez fidel orthography with timestamped accuracy.
Draft ready for review“Inviting your teammates” · 1 edit
03. Extract Insights
Don't just get text—get searchable, actionable data with automatic speaker identification and summaries.
From recordings to understanding.
Andebet doesn't stop at transcription. Search conversations, identify speakers, extract key moments, summarize interviews, and turn hours of audio into information you can actually use.
Try Andebet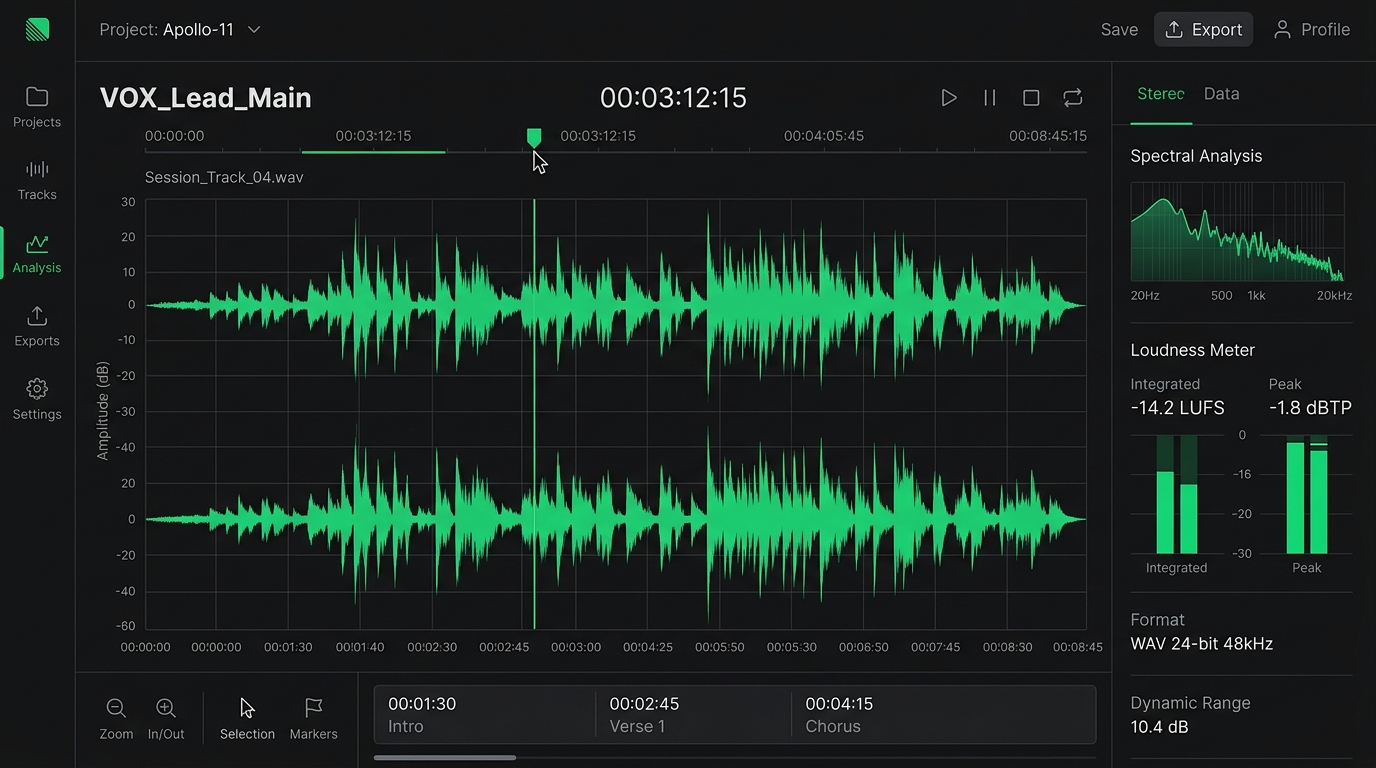
Handle mixed-language speech.
Keep Amharic, Afaan Oromo, Tigrinya, English, and code-switching in context.
Learn moreTime-aligned playback.
Jump from a transcript directly to the timestamp in the original recording.
Learn moreSearch every conversation.
Find a person, topic, phrase, or event across your recordings.
Learn moreUnderstand interviews faster.
Generate summaries, themes, key points, and structured insights.
Learn moreBatch audio processing.
Upload and process batches of recordings instead of working file by file.
Learn moreMulti-language models.
Full Ge'ez fidel and Latin Qubee orthography across Amharic, Afaan Oromo, and Tigrinya.
Learn morePrivate cloud & sovereignty.
Deploy on-premise or within isolated cloud VPCs to keep sensitive recordings confidential.
Learn moreCustom terminology.
Boost acoustic recognition for regional dialects, institutional acronyms, and legal terminology.
Learn moreBuilt for how people in Ethiopia actually speak.
Most transcription tools were built around English-first audio and fail when speakers switch languages. Andebet handles Ethiopian acoustic environments, tracks distinct speaker turns, normalizes Ge'ez fidel spelling, and links every sentence directly to its audio timestamp.
Transparent pricing for Ethiopian speech AI.
You only pay for what you process. Predictable transcription pricing for researchers, builders, and organizations. 45 free minutes included, no credit card required.
Free forever for exploring Ethiopian audio intelligence
For researchers, podcasters, and developers
For media teams, NGOs, and field research labs
Processing high volume or need dedicated infrastructure? Research & Enterprise tier includes 200+ hours at $149/mo.
Compare all features, overage calculators & ETB bank payment options →Frequently asked questions
Start transcribing Ethiopian audio today.
Start transcribing, searching, and analyzing your Ethiopian audio today. Create your free workspace account with 45 free minutes included.
How does Andebet process and transcribe Ethiopian audio recordings?
Andebet is a speech recognition and language intelligence platform built for Ethiopian and Horn of Africa languages. The system runs on neural Conformer acoustic architectures trained directly on 16kHz Ethiopian speech recordings across regional accents, including central Shewa, Gojjam, Wollo, and Gondar. In conversational Amharic benchmarks, the acoustic model records an 8.4% Word Error Rate and resolves 33 core fidel consonants across seven vowel orders. The text processing pipeline handles contextual Ge'ez homophone normalization for character sets such as ሀ/ሐ/ኀ, ጸ/ፀ, and ሰ/ሠ, and formats authentic Ethiopic punctuation marks including the two-dot word divider and four-dot section stop. Speaker diarization separates distinct voices with millisecond timestamps for multi-speaker interviews, meetings, and broadcast audio. Developers can connect directly through REST endpoints and Model Context Protocol integrations to query, transcribe, and index bilingual Amharic and English audio recordings.
Acoustic Benchmarks & Language Architecture Specifications
Andebet evaluates automated speech recognition accuracy across standard Ethiopian conversational benchmarks, comparing acoustic model parameters, Word Error Rates, and orthographic normalization capabilities.
| Language Target | Acoustic Model | Word Error Rate | Orthography Standard | Regional Dialects |
|---|---|---|---|---|
| Amharic (አማርኛ) | 16kHz Conformer CTC/AED | 8.4% WER | Ge'ez Fidel (33 core consonants, 7 vowel orders, homophone normalization) | Addis Ababa, Gojjam, Gondar, Wollo |
| Afaan Oromo | 16kHz Conformer CTC/AED | 9.1% WER | Latin Qubee (geminate consonants, long vowel markers) | Central Shewa, Hararghe, Wollega, Arsi-Bale |
| Tigrinya (ትግርኛ) | 16kHz Conformer CTC/AED | 9.7% WER | Ge'ez Fidel with Tigrinya labiovelar extensions (ቈ, ኈ, ኰ, ዀ) | Mekelle, Adwa, Shire, Asmara |
| Mixed Code-Switching | Multilingual Dynamic Tokenizer | 11.2% WER | Bilingual Amharic/English Fidel-Latin interlinear alignment | Urban broadcast, academic lectures, business meetings |
Multi-Speaker Diarization Pipeline
Interviews and qualitative focus groups frequently suffer from overlapping voices and acoustic reverberation. Andebet isolates speaker turns using neural x-vector voice embeddings combined with spectral clustering. Timestamp citations are generated at millisecond granularity, allowing researchers to click directly from a transcribed Fidel sentence to the corresponding spoken audio segment.
Supported Audio Containers & Codecs
Andebet accepts recordings in MP3, WAV, M4A, AAC, OGG Vorbis, FLAC, OPUS, and AMR telephony formats. Recordings are downsampled to 16,000 Hz single-channel PCM audio for acoustic inference. Telephony audio captured at 8kHz undergoes neural bandwidth extension to recover high-frequency consonant formants essential for Ge'ez fricative disambiguation.